SEO Tests That Actually Prove Causality: A Practical Incrementality Playbook for SMEs (and the Execution Gap Most Teams Miss)
Seeing organic traffic lift after a change doesn’t mean your change caused it. Here’s a practical, SME-friendly framework for SEO incrementality testing—how to build controls, avoid false positives, interpret results, and scale winners with an execution system that keeps changes safe and accountable.
Most SEO tests don’t fail because the idea was bad. They fail because the method couldn’t separate what you changed from everything else happening in search at the same time.
You ship a new Title tag pattern, internal link module, or Content refresh. Two weeks later, Organic traffic is up. Everyone celebrates. Then the lift disappears—or worse, it shows up on pages you never touched. That’s the moment you realize you measured “something changed,” but you didn’t prove your change caused it.
This editorial is a practical playbook for SMEs and lean teams who want SEO testing that stands up to scrutiny: not lab-grade perfection, but reliable enough to bet roadmap time on. It’s informed by the causality-first principles highlighted in Search Engine Land’s piece on why SEO tests fail, plus an execution reality most articles skip: even a great test is useless if you can’t roll it out safely and repeatedly.
Primary source: Search Engine Land – 7 reasons your SEO tests fail and how to fix them.
Concise summary
SEO testing is difficult because search is noisy: algorithm updates, seasonality, competitor moves, and tracking issues can all mimic “wins.” The fix is to treat SEO tests like incrementality experiments: define a clear hypothesis, create a comparable control group, measure outcomes beyond traffic (quality and conversions), and plan rollout/rollback before launch. Finally, operationalize results so you can scale winners fast without breaking the site—this is where an Approved Execution system like AYSA can turn insights into reliable outcomes.
Key takeaways
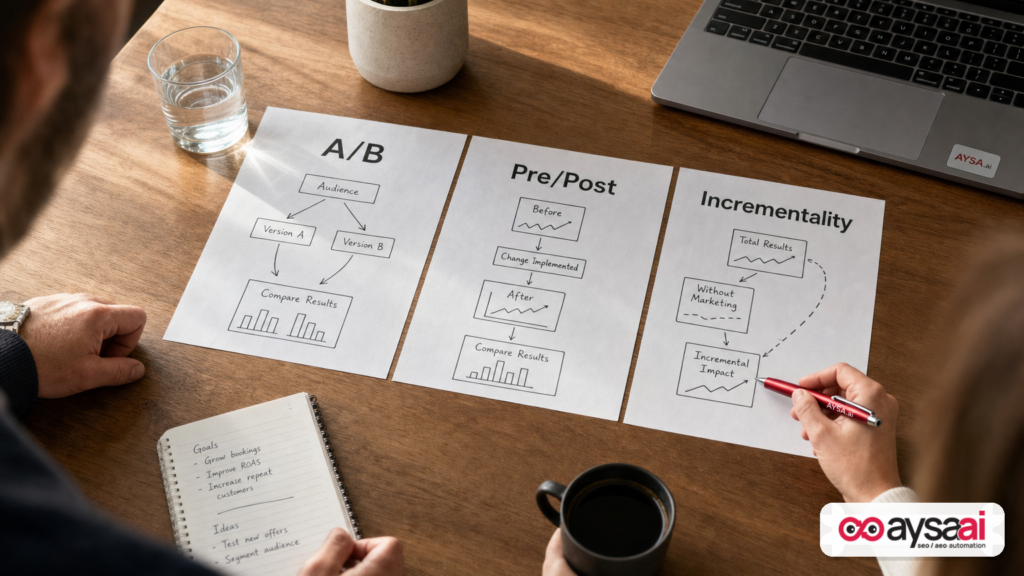
- A lift isn’t proof. Pre/post comparisons are directional; incrementality is how you isolate causal impact.
- Controls are non-negotiable if you want confidence—not just a story you tell yourself.
- Measure business outcomes (lead quality, Conversion rate, revenue proxies), not just sessions.
- Most SEO programs fail at execution. Tests “win,” but teams can’t ship, QA, and scale safely.
- Build a repeatable workflow for hypothesis → test → interpret → rollout → documentation.
Table of contents
- What changed in SEO testing (and why it matters in 2026)
- The hard truth: SEO changes happen in a noisy world
- The three SEO testing models (and when each one is valid)
- Incrementality testing, explained like you’re running a real business
- How to write hypotheses that survive reality
- Risk/reward: the missing step that protects revenue
- Building a control group without overengineering it
- What to measure: from rankings to revenue-quality signals
- Reading results without fooling yourself
- Knowing when a result is worth scaling
- The execution gap: why most SEO tests die after the results
- Where AYSA fits: monitoring + approved execution for SEO/AEO/GEO
- What to do next: a practical 30-day action list
- Sources and further reading
What changed in SEO testing (and why it matters in 2026)
SEO has always been hard to test because Google doesn’t give you a clean “on/off” switch for a change. But the stakes are higher now for three reasons:
- Search surfaces are fragmenting. You’re not only competing in classic “10 blue links.” Visibility increasingly shows up across Rich results, local packs, and AI-driven experiences. That means success can look like more impressions but fewer clicks, or different query mixes that change lead quality.
- Release velocity is faster. Most sites ship something weekly—content updates, design tweaks, tracking changes, pricing promos. If your test doesn’t isolate variables, it becomes impossible to attribute outcomes.
- Business expectations have matured. CEOs and founders want SEO to behave more like performance marketing: hypothesis-driven, measurable, iterative, and accountable. “Traffic is up” isn’t enough—especially for SMEs where one wrong change can hurt pipeline.
Search Engine Land’s framework is blunt and correct: most SEO tests fail due to flawed methodology, weak hypotheses, lack of controls, poor interpretation, and lack of follow-through (source). I agree—and I’ll add a fourth meta-problem I see constantly: even when teams get the analysis right, they can’t execute changes safely and consistently. That execution gap is where results die.
So the goal of this article is not to create “perfect science.” The goal is to build a repeatable business system that answers one question with enough confidence to act:
“If we roll this change out, will it produce incremental value—or are we chasing noise?”
The hard truth: SEO changes happen in a noisy world
If you’ve ever run an SEO test, you’ve felt this: you change something small, and the chart moves. You feel smart. Then you learn Google rewrote your title. Or a competitor got deindexed. Or demand spiked because of a seasonal trend. Or your paid team launched a campaign that altered brand query volume.
Here are the most common “noise sources” that create false positives (and false negatives):
- Seasonality: Local services, retail, travel, and healthcare all have predictable peaks and valleys.
- Algorithm volatility: broad changes, SERP layout updates, or query interpretation shifts can move rankings unrelated to your change.
- Competitor actions: new pages, link pushes, pricing changes, or simply better offers can shift CTR and conversions.
- Site releases: template updates, navigation changes, speed regressions, tracking modifications.
- Measurement drift: attribution windows, consent mode changes, tag manager edits, or broken event tracking.
Pre/post measurement (before vs. after your change) treats the world as stable. It isn’t. That’s why the foundational idea from Search Engine Land matters so much: incrementality testing is the gold standard because it isolates impact by comparing changed pages to unchanged but similar pages over the same period (source).
The three SEO testing models (and when each one is valid)
Let’s simplify the jargon.
1) A/B testing (split testing)
A/B testing sends real users to two versions of a page and compares behavior. It’s excellent for UX and conversion optimization, because you can attribute differences in conversion rate to the experience users actually saw.
But for SEO ranking impact, A/B testing is usually limited. Google doesn’t reliably index and rank two versions in a perfectly split way. You can test UX, content blocks, and conversion steps—but not “ranking impact” with the same certainty.
Use A/B tests when: you’re testing conversion elements (forms, CTAs, layouts), not expecting Google ranking changes to be the main outcome.
2) Pre/post (before/after) testing
This is the most common SEO test: change a set of pages and compare performance before vs. after. It’s fast and easy. It’s also the most likely to mislead you, because it doesn’t control for external variables (Search Engine Land calls this out explicitly; source).
Use pre/post when: you can’t create controls, you need directional guidance, or you’re validating a low-risk change. But treat the results as provisional.
3) Incrementality testing (test vs. control)
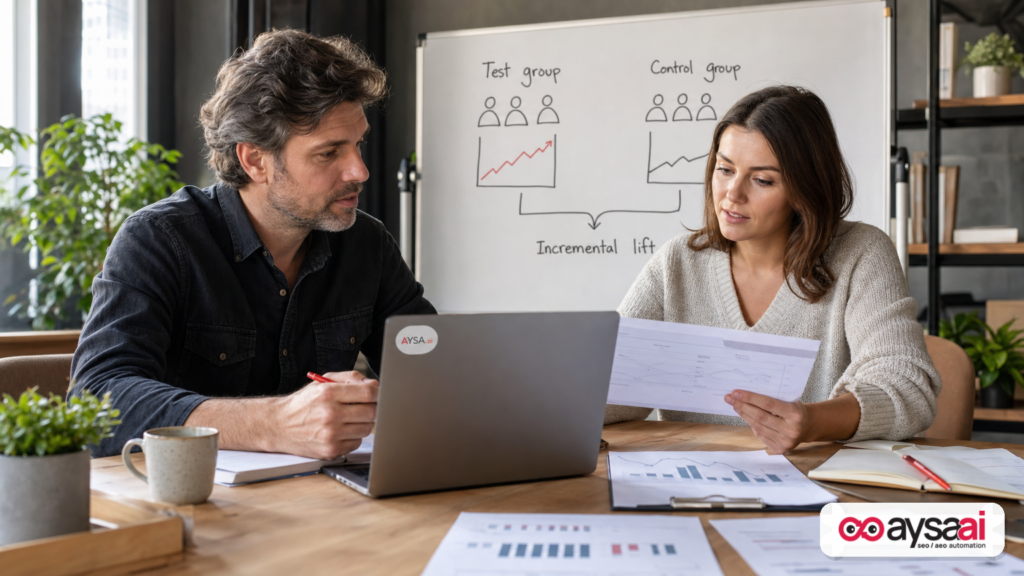
Incrementality compares a group that gets the change (test) against a similar group that does not (control) over the same time window. If both groups face the same seasonality, algorithm updates, and external conditions, then the difference between them is closer to your causal effect.
Use incrementality when: you want to know if a change caused the lift, and you need confidence to scale across hundreds of pages.
In practice: most mature SEO programs use a mix. But if you’re trying to turn SEO into an accountable growth lever, incrementality becomes the backbone.
Incrementality testing, explained like you’re running a real business
If you run a local clinic, an ecommerce shop, a hotel, or a SaaS company, you already understand incrementality—you just don’t call it that.
Imagine you’re testing a new intake script for your front desk. You wouldn’t judge it by comparing this week to last week if you also changed insurance partners, launched a radio ad, and added a new doctor. You’d try the script at one location (or one team) while keeping another as-is, then compare outcomes.
SEO incrementality works the same way:
- Pick a change (e.g., rewrite title tags in a pattern, add internal links, update product copy).
- Pick a set of comparable pages to change (test group).
- Pick a set of comparable pages to leave unchanged (control group).
- Run them during the same time window and compare deltas between groups.
You’re not trying to predict the entire market. You’re trying to answer: “Did this change produce incremental lift compared to what would have happened anyway?”
That’s the causality question. Everything else is interpretation.
How to write hypotheses that survive reality
A hypothesis is not “we think this will help SEO.” A hypothesis is a specific, measurable claim with a mechanism and a time horizon.
Search Engine Land emphasizes hypothesis rigor: make it actionable, consistent, measurable, and extensive enough to observe ranking impact (source). That’s right—and SMEs need an even more practical translation:
A usable hypothesis template
If we [make a specific change] on [a defined page set], then we expect [a measurable outcome], because [why Google/users would respond], measured by [metrics], within [time window].
Examples that work
- Ecommerce category pages: “If we add a short ‘How to choose’ section with internal links to top subcategories on 25 category pages, then we expect increased non-brand impressions and clicks on those pages versus control pages because the pages better match comparative intent and improve internal discovery.”
- Local service pages: “If we standardize H1s to match primary service + city on 30 location pages, then we expect improved ranking distribution for ‘service + city’ queries versus controls because the page’s primary topic is clearer.”
- SaaS feature pages: “If we restructure feature pages to include explicit problem/solution sections and FAQs, then we expect more long-tail query impressions and higher demo conversion rate versus controls because users find answers faster and intent alignment improves.”
Examples that fail (and why)
- “Update some content and see what happens.” (Not specific.)
- “Change one word across three low-traffic pages.” (Not enough volume; too small.)
- “Add schema and rankings will increase.” (Schema can help understanding and eligibility, but ranking impact isn’t guaranteed; the mechanism is weak unless tied to a specific SERP feature.)
Notice what’s missing: guaranteed outcomes. SEO isn’t deterministic. Your hypothesis should be falsifiable.
Risk/reward: the missing step that protects revenue
Testing culture in SEO often defaults to “ship and see.” That might work on a blog. It’s reckless on money pages.
Search Engine Land recommends a risk/reward analysis: consider worst-case scenarios, mitigate with QA, start small, avoid risky timing, and prepare a rollback plan (source). That guidance becomes even more important as sites rely on organic for pipeline.
A simple risk matrix for SMEs
Before you test, score the change on two axes:
- Business impact potential: low/medium/high
- Failure cost: low/medium/high (breakage, conversion loss, brand risk)
Then match your rollout strategy:
- High impact + high risk: staged rollout, tight monitoring, rollback trigger, avoid weekends.
- High impact + low risk: broader test set, shorter time-to-decision.
- Low impact + high risk: don’t test (or redesign the hypothesis).
- Low impact + low risk: bundle into maintenance releases, measure opportunistically.
QA basics that prevent catastrophic “test failures”
- Check rendering on mobile and desktop.
- Confirm indexability signals didn’t change (robots, canonicals).
- Verify tracking events still fire (forms, purchases).
- Confirm page speed didn’t regress severely.
- Set a rollback plan: who reverts, how fast, and under what threshold.
This isn’t red tape. It’s how you protect revenue while still moving fast.
Building a control group without overengineering it
If you’re an enterprise with a data science team, you can do sophisticated matching and statistical modeling. Most SMEs can’t—and don’t need to.
The goal of a control group is simple: create a set of pages that are similar enough that they experience similar external forces.
Search Engine Land’s point is direct: without a control group, you can’t compare test pages against “what would have happened otherwise” during the same period (source).
A practical control-building method
- Choose a page type: don’t mix apples and oranges. Product pages with blog posts is a mess. Start with one template type (e.g., category pages).
- Filter to eligible pages: pages that are indexed, stable, and have enough impressions/clicks to observe movement.
- Group by similarity: use simple rules: similar intent, similar traffic tier, similar position range (e.g., average position 8–20).
- Split into test/control: keep the distribution similar. Don’t put all the “strong” pages in the test group.
How many pages do you need?
There’s no universal minimum. But here’s the principle: the smaller the expected effect, the more pages and time you need. If you can only change five pages, don’t pick a change you expect to move the needle by 1%.
When in doubt, pick fewer changes but more pages—one variable, repeated consistently.
If you truly can’t create a control group
Sometimes you can’t (e.g., you must update every page for legal or brand reasons). In those cases, treat the test as pre/post, but add “reality checks”:
- Compare to overall site performance.
- Compare year-over-year where seasonality is strong.
- Segment by device and query type to detect shifts in mix.
It’s not perfect, but it prevents the worst self-deception.
What to measure: from rankings to revenue-quality signals
Many SEO tests “win” on traffic and lose on business impact. That’s not a win.
Search Engine Land recommends checking all your data, validating surprises, filtering results (desktop vs mobile), and guarding against outliers (source). I’d add: SMEs must define primary and secondary metrics upfront, or you’ll cherry-pick after the fact.
Core metrics to track
Visibility (leading indicators):
- Impressions (Google Search Console)
- Average position (directional, not absolute truth)
- Query mix (are you showing up for the right searches?)
Traffic (mid indicators):
- Clicks (Search Console)
- Sessions/engaged sessions (GA4)
Business outcomes (lagging but decisive):
- Lead submissions, calls, bookings, purchases (your actual conversion events)
- Conversion rate and revenue per session (where available)
- Down-funnel quality proxy: qualified lead rate, booked appointment rate, refund rate (if you have it)
Common measurement pitfalls
- CTR illusions: a title change can raise CTR without improving rank—or can raise impressions while lowering CTR. Interpret in context.
- Mix shifts: traffic goes up because you captured top-of-funnel informational queries that don’t convert.
- Device divergence: mobile improves while desktop worsens (or vice versa). You need segmentation.
Tooling baseline for SMEs
You can run credible tests with:
- Google Search Console for query/page performance (primary for SEO visibility). If you need the official entry point, start with Google Search Console.
- GA4 for onsite behavior and conversion events. Official overview: Google Analytics 4.
- Your CRM or ecommerce platform for lead quality and revenue outcomes.
(We’re linking to Google’s own documentation because it’s the most stable primary source for definitions and setup.)
Reading results without fooling yourself
This is where most teams go wrong—not because they’re careless, but because humans are wired to see patterns and claim credit.
Search Engine Land lists several interpretation mistakes: not checking all data, not validating surprises, going deeper than surface, filtering segments, and watching outliers (source). Here’s the practical “anti-self-deception” checklist I recommend.
The anti-self-deception checklist
- Did both groups experience the same external conditions? If a major update hit mid-test, extend the window or rerun.
- Did the query mix change? If you gained impressions for unrelated terms, your lift isn’t the lift you wanted.
- Are a few pages driving the result? If 2 pages account for 80% of the gain, you don’t have a scalable pattern yet.
- Did conversion rate change? If traffic grows but conversion rate drops, check lead quality and intent alignment.
- Is the change consistent across segments? Mobile/desktop, brand/non-brand, geo, new/returning.
- Can you confirm with a second view? For example, do Search Console clicks and GA4 sessions tell a compatible story? They won’t match 1:1, but they should rhyme.
Concrete SME scenario: the local clinic that “won” the wrong traffic
Picture a regional dental clinic with 20 location pages. The marketing manager tests new title tags emphasizing “affordable” and “same-day.” Traffic goes up 18% on test pages versus controls. It looks like a win.
Then the call center reports more price shoppers and fewer high-value treatment bookings. Conversion rate to booked appointments drops. The clinic didn’t gain incremental business value; it gained a different audience.
The right conclusion isn’t “title tags don’t matter.” The right conclusion is: this language shifted intent mix. Next test: titles that emphasize outcomes (“pain-free,” “cosmetic,” “implants”) on high-intent pages while keeping affordability messaging limited to financing pages.
That’s what good SEO testing does: it teaches you how searchers interpret your offer.
Knowing when a result is worth scaling
Even strong tests don’t automatically earn a full rollout. Scaling has a cost: dev time, content time, QA, risk, stakeholder attention, and opportunity cost.
Search Engine Land emphasizes setting up for rollout with high confidence and treating rollout like another test (source). That’s exactly right.
Practical rollout thresholds (non-statistical but useful)
Without inventing hard numbers, here are qualitative thresholds I’d want before scaling:
- Consistency: the majority of test pages improve relative to controls (not just a couple winners).
- Durability: the lift persists across multiple weeks, not just a short spike.
- Business alignment: conversions and lead quality hold steady or improve.
- Repeatability: you can define the change as a clear rule (a pattern), not a one-off rewrite that can’t be operationalized.
Treat rollout as the second experiment
Rollout is often where you discover the truth. If the effect disappears when you apply it broadly, your original test group wasn’t representative—or your implementation didn’t scale cleanly.
So the disciplined approach is:
- Test on a subset with controls.
- Roll out to a larger batch.
- Measure again using the same metrics and segmentation.
- Document what changed and what you learned.
The execution gap: why most SEO tests die after the results
This is the part many SEO testing guides don’t emphasize enough: getting “a result” is not the same as building growth.
Here’s the typical failure pattern I see in SMEs and agencies:
- Someone runs a test, exports charts, and shares a doc.
- Everyone agrees it worked.
- Then it sits in a backlog because implementation needs engineering time, approvals, QA, and release coordination.
- By the time it ships, other changes have occurred, and you can’t tell if the rollout worked.
Search Engine Land calls out the need to follow up on results: document, share, clarify scope, explain exclusions, and define next steps (source). This isn’t “nice to have.” It’s the bridge between learning and compounding.
What to document every single time
- Hypothesis and why it mattered.
- Test and control page lists (or rules used to generate them).
- Exact change details (what changed, where, when).
- Measurement window and metrics.
- Results (including segments and negative outcomes).
- Decision: scale, iterate, or revert—plus rationale.
- Rollout plan and monitoring plan.
Why execution is harder than analysis
Analysis happens in one person’s spreadsheet. Execution touches your whole business: brand, legal, engineering, merchandising, sales ops, analytics, and customer support.
If your SEO testing program isn’t paired with an execution system, it becomes “insights theater.” That’s why I like tools and workflows that close the loop: monitor → recommend → approve → execute → measure → document.
Where AYSA fits: monitoring + approved execution for SEO/AEO/GEO
AYSA is built around a simple reality: most teams don’t fail because they lack ideas. They fail because they can’t reliably ship and verify changes without introducing risk.
Here’s how AYSA fits naturally into a causality-first SEO testing program:
1) Monitor what matters before you test
If you don’t have a baseline, you don’t have a test. AYSA’s monitoring layer helps teams keep visibility on site changes and performance signals so you can detect when “noise” enters your measurement window.
Explore monitoring: AYSA Monitoring
2) Align SEO with AI search visibility outcomes
Even when your goal is classic SEO traffic, modern search journeys increasingly include AI-assisted discovery. A good test framework should consider whether a change improves clarity, entity understanding, and content usefulness—signals that matter beyond blue links.
Learn about AI search visibility: AI Search Visibility
3) Use AI SEO tools to prepare changes—then require approval
AI can draft metadata patterns, propose internal links, rewrite sections, or generate test variants. The danger is letting AI “auto-ship” without safeguards. AYSA’s model is to prepare work and ask for approval before executing accepted website changes—exactly the discipline SEO testing needs.
AI SEO tools overview: AI SEO Tools
4) Make execution repeatable and accountable
The difference between occasional SEO wins and sustained growth is process. When your system can track what changed, when, and why—and coordinate approvals—you get compounding returns from testing instead of one-off experiments.
Pricing and plans: AYSA Pricing
5) Build institutional knowledge
Most SMEs lose SEO learnings when people leave or agencies rotate. Documentation turns tests into assets. Your testing log becomes strategy.
More playbooks: AYSA Blog
What to do next: a practical 30-day action list
If you want to run SEO tests that stand up to scrutiny—without building a data science department—here’s a step-by-step action list you can start this month.
Week 1: Pick one business-critical page type and define success
- Choose one template type (e.g., service pages, category pages, location pages).
- Define the business outcome: leads, bookings, sales, qualified inquiries.
- Confirm baseline tracking: Search Console connected; GA4 conversion events reviewed.
Week 2: Build your test design (hypothesis, groups, risk plan)
- Write one hypothesis using the template in this article.
- Select test pages and control pages with similar intent and traffic tier.
- Create a risk plan: QA checklist, monitoring cadence, rollback triggers.
Week 3: Execute the change safely
- Implement the change consistently across the test group only.
- Verify pages render, indexability is intact, and conversions still track.
- Document the exact change and timestamp.
Week 4: Measure, interpret, decide
- Compare test vs control deltas on impressions, clicks, query mix, and conversions.
- Segment by device and brand/non-brand where possible.
- Decide: scale, iterate, or revert—and write down the reasoning.
Then repeat—with one improvement
The best SEO testing programs get better every cycle. Each test should improve:
- your hypotheses (more precise),
- your controls (more comparable),
- your measurement (more tied to business), and
- your execution (faster, safer rollouts).
What to do next (quick checklist)
- Stop declaring wins from pre/post charts alone. Add controls or at least site-wide and YoY comparisons.
- Pick one variable per test. Avoid bundling changes unless your goal is a package rollout.
- Decide your “business metric” upfront. Traffic without outcomes is vanity.
- Plan the rollout before the test starts. Execution is part of the methodology.
- Document every test. Your test library becomes strategy.
- Use an execution system. Monitoring + approvals + implementation discipline prevents accidental damage and speeds scaling.
Sources and further reading
- Search Engine Land: 7 reasons your SEO tests fail and how to fix them
- Google Search Console (official)
- Google Analytics 4 overview (official)
- Search Engine Land: Schema for AI search: How to identify and prioritize entity gaps
- Search Engine Land: The new SEO rules for bloggers in 2026: Why clarity matters in AI search
- Search Engine Land: How semantics and topical authority improve local SEO
Relevant AYSA links
Continue the AI search topic inside AYSA.
Use these pages to connect the article with AI SEO tools, AI visibility monitoring, AI Overviews and approved website execution.
Turn this topic into a website action plan.
Use these AYSA hubs to move from reading to technical fixes, AI visibility monitoring, research, glossary context and approval-first SEO execution.