Meta’s New Crawling Terms: What SMBs, Ecommerce Teams, And Agencies Should Do Before “Training Rights” Become Default
Meta’s updated Commercial Terms expand crawling and AI training rights from “advertisers” to essentially any business using Meta products. Here’s what changed, why robots.txt may not be the whole answer, and a practical, execution-first playbook for SMBs and agencies.
Meta quietly moved a big lever: updated terms that can allow Crawling and downstream “product improvement” (including training) to attach not just to advertisers, but to any business using Meta products. If you run a Facebook Page, manage a catalog, message customers, or use Meta’s business tools—even without buying ads—this matters.
This isn’t about panic. It’s about governance. AI discovery is expanding, and the businesses that win will be the ones that can clearly answer two questions: (1) What content are we comfortable having crawled and learned from? and (2) How fast can we implement and maintain that decision across our site, feeds, and publishing workflow?
Below is my practical, execution-first playbook for SMBs and agencies—written from the perspective of building AYSA.ai, where we monitor changes, prepare recommendations, ask for approval, then execute accepted changes on your site.
Concise summary
- What changed: According to reporting by Search Engine Journal, Meta updated its Commercial Terms to allow crawling of websites connected to businesses using Meta products—and use that content to develop, improve, and train Meta products. The same crawl permission also appears in revised self-serve ad terms, but the key difference is the broader “business use” scope.
- Why it matters: This moves crawling/training permission from an “advertising contract” into something closer to “default platform participation” for many businesses.
- What to do: Audit what content is exposed, decide what should be crawlable vs. protected, review Robots.txt by crawler token, and tighten technical/content governance—especially for paywalled, gated, or proprietary pages.
- Where AYSA fits: AYSA helps you monitor crawling and visibility shifts, proposes changes (robots directives, Indexing controls, content architecture updates), routes them for approval, then executes and validates the implementation.
Key takeaways (for busy operators)
- If you use Meta for business, assume your website content could be eligible for crawling under the updated terms—even if you don’t buy ads.
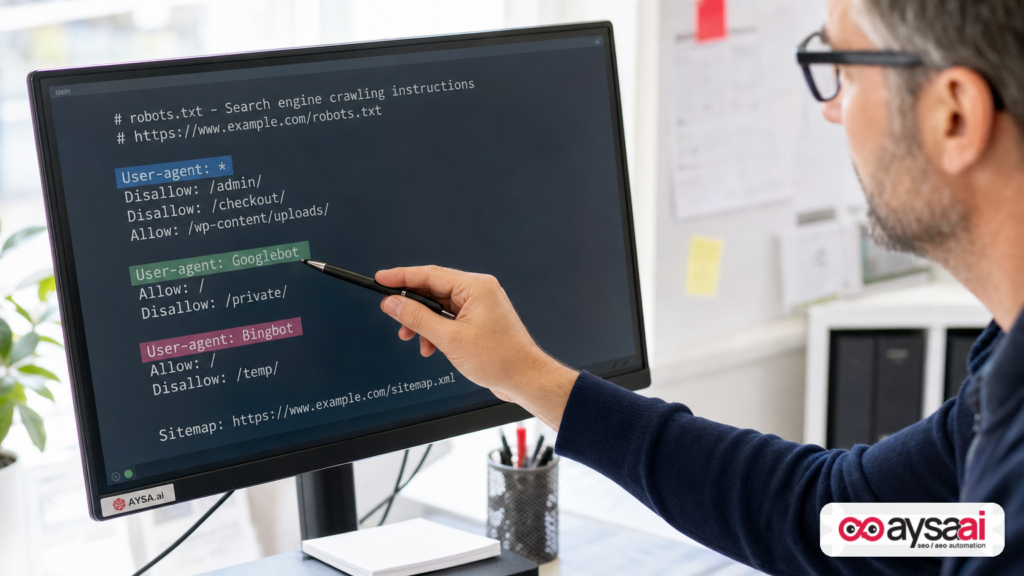
- Robots.txt is a lever, not a legal shield. It can reduce access by specific crawlers, but terms and technical behavior don’t always align perfectly.
- Different Meta crawlers may have different purposes (e.g., training vs. search indexing), so “block Meta” is often an overly blunt instrument.
- Content governance now belongs in SEO strategy. Your catalog, landing pages, help docs, UGC, and gated resources aren’t just marketing—they’re training data.
- Execution speed matters. Policies change faster than most sites can implement technical updates; the advantage goes to teams with an approval-to-deploy workflow.
Table of contents
- What Actually Changed: Meta’s Crawling Rights Expand Beyond Advertisers
- Why This Is Happening Now: AI Discovery Replacing Traditional Referral Patterns
- Robots.txt Is Not A Strategy (But It’s Still A Lever)
- The “Test Credentials” Clause: Gated Content, Paywalls, And Registration Walls
- A Practical Risk Map: What Content Types Are Most Exposed?
- A Concrete SMB Scenario: The Ecommerce Brand That Doesn’t Run Ads (But Still Has “Business Use”)
- What Agencies Should Rethink: Terms, Deliverables, And Technical Governance
- How This Changes Search Behavior: From Rankings To “Training Eligibility”
- Two-Week Action Plan: What To Do Before Terms Take Effect
- Where AYSA Fits: Monitoring, Recommendations, Approval, Execution
- What to do next (checklist)
- Sources and further reading
What Actually Changed: Meta’s Crawling Rights Expand Beyond Advertisers
The core development is reported by Search Engine Journal in “Meta’s New Terms Expand Crawling Rights Beyond Advertisers.” It describes Meta’s updated Commercial Terms taking effect Oct. 30, granting Meta permission to crawl websites associated with businesses that use Meta products and to use collected content to develop, improve, research, and train products.
There are two shifts here that operators should internalize:
- Scope shift: Historically, many businesses associated “platform crawling rights” with ad programs (you buy ads, you grant certain permissions). The reporting indicates the updated language is tied to business use broadly—like running a Page, managing a catalog, or using business tools—not just ad buys.
- Purpose shift: Crawling isn’t framed only as ad verification or link previews. It’s connected to product development and training—which, in the current AI era, can have lasting implications.
Meta has publicly disputed some interpretations of the reporting, stating (as cited by SEJ) that the update is intended to pull accurate product information for recommendations and that it’s “not about scraping news sites.” That clarification matters, but it doesn’t eliminate the operational reality: the terms define what Meta believes it may do, and businesses must decide how to respond.
Primary research input: Search Engine Journal coverage.
What this is not
This is not a claim that Meta will crawl every page of every business site, or that it will train on every piece of crawled content. The reporting covers the permission structure and the clause language, plus how legal professionals interpret potential enforceability. Implementation details can vary—and if we can’t verify behavior, we should treat it as risk analysis, not a fact pattern.
But permissions matter, because permissions influence:
- What crawlers are deployed
- What content gets prioritized
- What disputes look like later (especially around copyright, Attribution, and content monetization)
Why This Is Happening Now: AI Discovery Replacing Traditional Referral Patterns
For years, “traffic” meant Google rankings and maybe some paid social. Now discovery is increasingly mediated by AI: assistants, in-app search experiences, and recommendation systems that synthesize information instead of simply linking to it.
Meta has been building AI-driven experiences across its apps, and SEJ’s reporting references crawler documentation that distinguishes between training-related crawling and search indexing crawling.
From an operator’s perspective, this is the new landscape:
- Search to discovery: Users don’t always start with a query. They start with a feed, a message thread, a “recommended for you” unit, or an in-app AI answer.
- Links are no longer the only currency: Being cited matters, but so does being “understood” by the AI system generating an answer or suggestion.
- Catalogs and structured content become training-grade assets: Your product pages, FAQs, policy pages, and how-to content can be consumed at scale.
That’s why this terms update is bigger than legal fine print. It’s a signal: platforms want broader, more durable rights to ingest the open web and business web, because that ingestion fuels AI features users increasingly expect.
Robots.txt Is Not A Strategy (But It’s Still A Lever)
Meta (per SEJ’s reporting) points businesses to robots.txt as a way to manage crawler access. And yes—robots.txt is one of the cleanest, lowest-cost control points you have.
But here’s my operator take: robots.txt is a tactic. Your strategy is content governance. The difference matters because:
- Robots.txt is voluntary compliance. It’s a protocol widely respected, but it isn’t an access control system like authentication.
- Robots directives can be misconfigured. SMB sites commonly inherit old directives, plugin-generated rules, or staging rules that accidentally ship to production.
- Different crawlers have different roles. Blocking everything might also block legitimate indexing/citation benefits—depending on how the platform uses that content.
Meta crawler tokens: treat them as separate decisions
SEJ’s extracted text references Meta crawler documentation naming different agents (e.g., one for AI training/model improvement vs. one for AI Search indexing). Practically, that means you may not want a single “yes/no” answer for Meta crawling.
A more mature posture is:
- Allow crawlers that support attribution and citation (if that aligns with your growth goals).
- Restrict crawlers used for broad training if you’re a publisher, have proprietary content, or monetize access directly.
- Authenticate anything truly sensitive (because robots directives don’t protect secrets).
Important nuance: Terms language and robots directives can collide. SEJ’s reporting notes legal experts suggesting that platform terms may be argued to supersede blocking instructions. We can’t validate how any court would rule, but as a business operator, you should plan for “robots.txt + legal terms” uncertainty.
Robots.txt best practices (SMB-safe)
If you haven’t touched robots.txt since your site launched, that’s already a risk. Here’s what “good hygiene” looks like:
- Keep it intentional: Every disallow line should have a reason your team can articulate.
- Separate bots: If you’re making decisions by user-agent, document why.
- Validate changes: Treat robots changes like code: staging, review, deploy, verify.
- Don’t rely on robots for protection: If it would hurt you if it leaked, put it behind auth.
This is one place where execution systems matter: a single misplaced wildcard can quietly de-index important pages or block beneficial crawlers, and SMBs often don’t discover it until revenue dips.
The “Test Credentials” Clause: Gated Content, Paywalls, And Registration Walls
One of the more operationally sensitive parts of SEJ’s reporting is the mention that the clause allows Meta to “create test credentials” to access pages. A Cornell law professor (as cited) raised the idea that this could allow access past registration walls.
We can’t verify how Meta will use this, and SEJ notes Meta declined to answer whether it would bypass paywalls or paid content. So treat this section as risk analysis, not an accusation.
Here’s the practical takeaway: if you monetize gated access, you need a technical enforcement model—not just a “please don’t crawl” model.
What to check if you have gated content
- Is your “paywall” actually a paywall? If content is in the HTML and merely hidden by CSS/JS, it’s not protected.
- Do you expose full content to logged-out users via prefetching? Some sites accidentally do.
- Do you have member-only URLs indexed? Even if they require login, the URL itself can leak sensitive taxonomy and patterns.
- Are your terms-of-service aligned with your technical enforcement? If you say “no automated access,” but your site allows it, you’re relying on policy instead of controls.
A Practical Risk Map: What Content Types Are Most Exposed?
Most SMBs don’t need a legal war room. They need a content asset inventory and a few clear categories. Here’s a simple risk map you can run in an afternoon.
Category 1: “Public marketing” content (usually okay to crawl)
- Home page, category pages, service pages
- Product pages meant for discovery
- Store hours, locations, policies
- Press releases you already distribute publicly
Why: This content is designed to be seen, referenced, and recommended.
Category 2: “Differentiation” content (decide intentionally)
- In-depth buying guides
- Original research and comparison pages
- Unique recipes, patterns, training methods, frameworks
- High-performing landing pages that you A/B test
Why: This is where your business advantage lives. Letting it be broadly ingested may or may not align with your strategy, depending on how you monetize and compete.
Category 3: “Sensitive/proprietary” content (protect technically)
- Wholesale pricing tables
- Customer-specific portals
- Internal documentation accidentally exposed
- Partner-only integration docs
- Inventory feeds or endpoints not intended for public use
Why: Even “well-behaved” bots can misinterpret; and not all bots are well-behaved. Use authentication and proper access controls.
Category 4: “User-generated content” (UGC) (watch consent and governance)
- Reviews
- Community Q&A
- Forums
Why: UGC often contains personal data or sensitive details. Even if legal consent is handled, brand risk (and privacy risk) increases when content is repurposed broadly.
A Concrete SMB Scenario: The Ecommerce Brand That Doesn’t Run Ads (But Still Has “Business Use”)
Let’s make this real.
Scenario: You run a mid-sized ecommerce business selling specialty home goods. You don’t run paid ads right now. But you do:
- Maintain an active Facebook Page
- Use Meta Business Suite to respond to customer messages
- Occasionally upload product information to keep your catalog up to date
- Encourage customers to share your product links on social
In the old mental model, you might think: “We’re not advertisers; platform crawl terms shouldn’t apply.” SEJ’s reporting suggests that assumption may no longer hold, because the grant is connected to business usage broadly.
Where businesses get blindsided:
- Your “business use” footprint grows quietly (Page + catalog + messaging).
- Your site grows too (blog posts, help docs, FAQs, sizing guides).
- Suddenly you realize your most valuable content isn’t just powering Google traffic; it’s eligible to power in-app AI recommendations somewhere else.
What I would do in this ecommerce scenario:
- Decide what you want AI discovery to do for you. For many ecommerce brands, broad crawling of product pages is a feature, not a bug—because it can improve citation and product understanding.
- Separate “product truth” from “competitive advantage.” Make product attributes and policies easy to crawl; keep supplier strategy and operational playbooks protected.
- Harden the edges. Lock down feed endpoints, remove accidental indexing of account pages, and ensure robots directives match your strategy.
- Instrument the change. Watch server logs (or CDN logs) and performance signals after updating directives so you can see what changed.
This is how grown-up SEO works now: it’s not just “rank and publish.” It’s governance, control points, and feedback loops.
What Agencies Should Rethink: Terms, Deliverables, And Technical Governance
If you’re an agency, this is not just “client education.” It’s a retainer problem.
Historically, agencies sold:
- Rankings
- Content production
- Link Building
- Technical audits (quarterly, maybe)
But as platform terms expand, clients will increasingly ask:
- “Who is crawling our site, and for what?”
- “Can we be cited without being trained on?”
- “Which pages should be excluded from automated collection?”
- “If we change directives, who maintains them and verifies impact?”
That pushes agencies toward ongoing governance deliverables:
- Crawler policy management: maintaining a documented stance by bot purpose.
- Technical enforcement: ensuring gating is real gating, not superficial.
- Content classification: mapping “public vs. differentiation vs. proprietary” content.
- Approval workflows: clients need to approve policy-level changes; agencies need a system to implement them safely.
In other words: execution becomes the product, not the PDF audit.
How This Changes Search Behavior: From Rankings To “Training Eligibility”
Even if your traffic still comes mostly from Google today, it’s dangerous to treat this as a “Meta-only” issue. The broader pattern is that AI products rely on large-scale ingestion of web content.
So the question becomes: What is your business optimizing for?
Old SEO worldview
- Rank #1
- Get the click
- Convert on-site
New AEO/GEO worldview
- Be the recommended option (or the cited source)
- Be accurately understood (entities, attributes, policies, constraints)
- Win “selection,” not just “Impressions”
- Keep control over what is commoditized vs. what remains proprietary
This is why we treat AI search visibility as a measurable discipline, not vibes. If you care about how your brand appears inside AI answers, you need monitoring and iteration.
Related AYSA resources:
Two-Week Action Plan: What To Do Before Terms Take Effect
SEJ’s reporting notes a limited window before the updated terms take effect. Whether you’re reacting specifically to Meta’s timeline or just using it as a forcing function, here’s a practical two-week plan that SMBs can execute without building an internal legal/SEO department.
Week 1: Inventory + decisions
- List your Meta “business use” touchpoints. Do you manage a Page? use Business Suite? have a catalog? run messaging? accept Marketplace activity? (Keep it simple: yes/no.)
- Inventory your web content types. Product pages, blogs, help center, gated content, UGC, partner docs.
- Classify content into four buckets: public marketing, differentiation, sensitive/proprietary, UGC.
- Decide your stance by bucket:
- Allow broad crawling
- Allow search/indexing but restrict training-oriented crawling
- Restrict crawling and add authentication
- Write it down. One page is enough. If it’s not documented, it won’t be maintained.
Week 2: Implementation + validation
- Review robots.txt for existing rules. Look for old blocks, staging artifacts, and conflicting directives.
- Check for accidental public exposure. Member pages, internal PDFs, endpoints, parameterized URLs.
- Implement targeted directives. If the goal is “allow indexing but restrict training,” do it by user-agent where possible (and document why).
- Enforce real access control for proprietary content. Authentication, paywall enforcement, proper cache control, and server-side checks.
- Validate with logs and crawl behavior. Watch for bot hits, status codes, and any unexpected crawl spikes.
- Review Meta-facing surfaces. If you publish catalogs or URLs through Meta tools, ensure they correspond to pages you want accessible.
Operational note: if you’ve never looked at server/CDN logs, this is where many SMBs get stuck. You don’t need perfection. You need enough observability to know whether changes took effect.
Where AYSA Fits: Monitoring, Recommendations, Approval, Execution
Most businesses don’t lose in SEO because they lack ideas. They lose because they can’t execute safely and consistently. Terms change, bots evolve, and the website becomes a patchwork of plugins, themes, and “temporary” fixes.
AYSA is built around a simple model that fits this moment:
- Monitor: Track visibility signals and site conditions that indicate risk or opportunity.
- Prepare: Generate prioritized recommendations (technical and content) aligned with your goals.
- Ask for approval: You stay in control—especially on governance issues like crawling directives and content exposure.
- Execute: Implement accepted changes and validate outcomes.
Relevant AYSA links:
What AYSA would do in a “Meta crawler terms” situation
Without pretending we can “solve” legal terms, AYSA can help operationalize your decisions:
- Baseline your site’s crawl posture (current robots directives, indexation patterns, exposed endpoints).
- Identify high-risk URL clusters (gated areas, thin parameter pages, internal search results, UGC sections).
- Draft a crawl policy change plan that separates “index/cite” goals from “training ingestion” concerns.
- Route it for your approval because these are business decisions, not just technical ones.
- Execute changes and verify using measurable signals and post-deploy checks.
This is the difference between “we should update robots.txt” and “we updated it, verified it, and ensured it didn’t break revenue pages.”
What to do next (action checklist)
- Today: List your Meta business touchpoints and the URLs you intentionally provide through Meta tools.
- Within 48 hours: Classify your website content into public / differentiation / proprietary / UGC.
- This week: Review and document your robots.txt stance by crawler purpose (don’t default to all-or-nothing).
- This week: Audit gated content and confirm it’s actually protected server-side.
- Next week: Implement changes with a rollback plan and validation checks.
- Ongoing: Monitor crawl patterns and AI discovery visibility as a normal operating rhythm—not as a one-time compliance task.
Sources and further reading
- Search Engine Journal: Meta’s New Terms Expand Crawling Rights Beyond Advertisers (research input)
- Search Engine Journal: AI Search coverage (broader context)
- Search Engine Journal: Technical SEO coverage (implementation context)
Note: The SEJ reporting references Meta crawler documentation and legal commentary. This editorial does not assume any specific enforcement outcome in court and does not claim any specific crawler behavior beyond what’s described in the cited reporting. If you need legal advice about platform terms or copyright, consult qualified counsel.
Continue the AI search topic inside AYSA.
Use these pages to connect the article with AI SEO tools, AI visibility monitoring, AI Overviews and approved website execution.
Turn this topic into a website action plan.
Use these AYSA hubs to move from reading to technical fixes, AI visibility monitoring, research, glossary context and approval-first SEO execution.