Robots.txt In The AI Search Era: Practical Crawl Control For SEO, AEO, And Real-World Business Outcomes
Robots.txt used to be a technical housekeeping file. Now it’s a business decision: what you let search engines crawl, what you allow AI tools to retrieve for users, and what you block from training. Here’s how to build a modern robots.txt policy that protects crawl budget, avoids indexation mistakes, and fits an AI search strategy—with an execution plan you can actually run.
By Marius Dosinescu, AYSA.ai
Robots.txt used to be “that file you set once” and forget. In 2026, that mindset is expensive. Not because robots.txt suddenly became complicated, but because the world around it changed: search crawlers still matter, but now AI training crawlers, AI Retrieval bots, and user-requested “fetch” agents also hit your site—often with different rules, different expectations, and different business implications.
If you manage a website that sells, books, generates leads, or publishes content, you’re now making three decisions in one place:
- What search engines may crawl (crawl efficiency and index quality).
- What AI systems may use for training (content licensing and competitive concerns).
- What AI tools may fetch for users in real time (visibility, citations, and conversions from AI answers).
This editorial is a practical, business-first guide to robots.txt as part of modern crawl management. It’s grounded in the excellent technical overview from Search Engine Journal (SEJ) on robots.txt best practices for search and AI crawlers, which you should read for additional context: Robots.txt Guide – Best Practices For Search & AI Crawlers.
My goal here is different: help you turn robots.txt into an operational policy your business can execute safely, monitor continuously, and adapt as AI Search evolves. And yes—this is exactly the type of change-management work that benefits from an “Approved Execution” system like AYSA: monitor what matters, prepare changes, ask for approval, then execute the accepted updates with verification built in.
Concise Summary
- Robots.txt controls crawling, not Indexing. Blocking URLs can still allow them to appear in search as “URL-only” results if they’re linked elsewhere.
- Conflicting rules resolve by precedence and specificity. Small syntax mistakes can silently block revenue-driving pages or crucial rendering assets.
- AI changes the stakes. You can often separate training bots from retrieval bots—meaning you can block training while still allowing AI tools to find and cite your pages for users.
- SMEs usually need crawl control for internal search, filters, and action URLs (add-to-cart, wishlist), not for marketing tracking parameters by default.
- Execution discipline matters more than theory. Treat robots.txt like a production release: plan, test, deploy, verify, and monitor logs and Search Console.
Key Takeaways (Business-First)
- Robots.txt is now a cross-functional decision. SEO, engineering, legal, and brand teams may all have a stake when AI training is involved.
- Blocking the wrong bot can reduce future visibility. You might keep a crawler out of training, but accidentally block retrieval/search bots that help you get cited in AI answers.
- Letting everything crawl can be just as harmful. Infinite URL spaces (filters, internal search, session IDs) waste server resources and dilute signals.
- Robots.txt won’t protect private content. Use authentication and access controls; robots.txt is not security.
- Monitoring is not optional anymore. AI bots and search bots evolve; you need ongoing visibility into what’s being requested and what’s being blocked.
Table Of Contents
- The New Robots.txt Reality: One File, Three Types Of Crawlers
- What Robots.txt Is (And What It Is Not)
- How Robots.txt Actually Works (And Why Most Teams Get It Wrong)
- Why Robots.txt Still Matters For SEO (Even In An AI World)
- High-Impact Use Cases: What To Block (And Why)
- UTM Parameters: When To Leave Them Alone
- PDFs And Non-HTML Assets: Crawl, Index, Or Noindex?
- AI Bots: Separate Training From Retrieval (And Don’t Guess)
- Crawl-Delay, Rate Limiting, And When Robots.txt Is Not Enough
- Testing And Troubleshooting: Don’t Deploy Blind
- The SME Scenario: An Ecommerce Store Accidentally Blocks Revenue Pages
- A Practical Action Plan: Your Robots.txt Policy In 30–60 Minutes
- Where AYSA Fits: Monitoring + Approved Execution For Crawl Policy
- What To Do Next
- Sources And Further Reading
The New Robots.txt Reality: One File, Three Types Of Crawlers
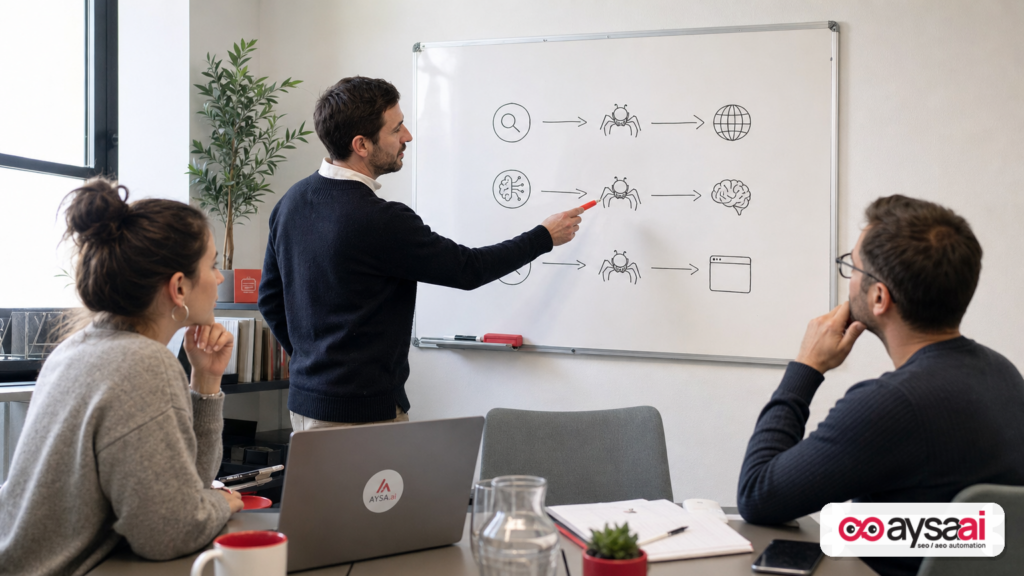
Historically, robots.txt was mostly about search engines. That’s no longer the full picture.
Today, your site can be accessed by:
- Search crawlers (indexing-focused, e.g., traditional web search bots).
- AI training crawlers (collecting content to train foundation models).
- AI retrieval and “user-requested fetch” bots (pulling pages in real time to answer a user’s question or to browse on their behalf).
SEJ’s guide puts this distinction front and center—and it’s the single most important mental model shift for business leaders. You’re no longer optimizing for “Googlebot vs everyone else.” You’re setting policies for how your content is used across search visibility, AI visibility, and content control.
My take: robots.txt is now part of your company’s distribution strategy, not just technical SEO hygiene.
What Robots.txt Is (And What It Is Not)
Robots.txt is a plain text file located at the root of a host (for example, https://www.example.com/robots.txt) that provides crawl directives to compliant crawlers.
Robots.txt typically uses a small set of directives:
- User-agent: which crawler the rules apply to.
- Disallow: request that a crawler not crawl matching URL paths.
- Allow: allow specific paths even under a broader Disallow.
- Sitemap: provide the location of your XML sitemap(s).
What it is not:
- Not a guarantee of deindexing. A blocked URL can still appear in search if it’s linked externally; the crawler may show it without crawling content.
- Not security. It does not protect sensitive content. Use authentication, authorization, and appropriate server controls.
- Not a full regex engine. As SEJ notes, robots.txt matching is limited. Common implementations use only
*(wildcard) and$(end-of-URL) patterns; treat matching rules as simple pattern checks, not programming logic.
How Robots.txt Actually Works (And Why Most Teams Get It Wrong)
Robots.txt seems simple until you remember two uncomfortable truths:
- Multiple teams touch it (SEO, engineering, agencies, platform vendors).
- A tiny change can have outsized impact (suddenly Google can’t crawl product pages—or can crawl a million pointless filter URLs).
1) Precedence: Specific User-Agent Groups Beat The Wildcard
If you have a general group (User-agent: *) and a specific group (e.g., User-agent: Googlebot), compliant crawlers use the rules in the most specific matching group.
That’s powerful, but it’s also where mistakes happen: one “temporary” group for a bot can override your carefully tuned default policy.
2) Specificity: The Most Specific Matching Rule Typically Wins
Within a group, when Allow and Disallow conflict, many crawlers choose the rule with the most specific match (longest/most precise path). SEJ highlights Google’s behavior here: the more specific match applies; if ties happen, the least restrictive rule may win.
Business implication: if you’re using Allow exceptions, you must test them. The human brain is bad at predicting which line “wins” across dozens of directives.
3) URL Path Matching Is Often Case-Sensitive
SEJ notes that path matching is case-sensitive in practice (e.g., filter= vs Filter=). That’s a common source of leaks: you think you blocked a parameter, but your site sometimes generates a different casing, and now bots crawl it anyway.
The Biggest Robots.txt Mistake: Treating It Like A Single Purpose Tool
If you only ask “Should Google crawl this?” you miss the AI layer. If you only ask “Should AI train on this?” you may accidentally block retrieval bots that could cite you and drive customers. In 2026, the question is: which class of bot is this, and what is our policy for that class?
Why Robots.txt Still Matters For SEO (Even In An AI World)
We’re in an era where everyone is obsessed with AI answers, AI Overviews, and agentic browsing. It’s tempting to think technical crawl management is “old SEO.” It’s not.
Robots.txt still matters because:
- Crawl efficiency affects index quality. If bots waste time on junk URLs, they may discover and refresh important pages slower (especially on large sites).
- Server stability is a real business constraint. A runaway crawl can spike infrastructure cost or degrade site performance for customers.
- Index bloat is a brand and conversion problem. Low-value pages in search create poor landing experiences, weaker engagement, and confusing brand presence.
- Sustainability and compute efficiency are increasingly part of the conversation. SEJ notes that reducing wasted crawling also reduces compute waste—this is both cost and responsibility.
Important nuance from SEJ: blocking doesn’t magically “reassign” crawl budget unless your site is already at crawl capacity limits. But for many sites—especially ecommerce with massive parameter spaces—robots.txt remains one of the most practical levers to avoid infinite crawl traps.
High-Impact Use Cases: What To Block (And Why)
Robots.txt is best used when URLs exist for user experience or application behavior—but not for search visibility. Below are the most common high-impact candidates, with practical framing and examples adapted from the SEJ research.
1) Internal Search Result Pages
Internal search pages are one of the most common sources of crawl waste and index mess. They often create:
- Near-infinite URL combinations.
- Thin, duplicate, or unstable content.
- Pages that change constantly (query-dependent), which isn’t great for indexing quality.
SEJ’s example (common on WordPress) is internal search using a query parameter like ?s=. A typical pattern to reduce crawling is to disallow internal search query URLs while keeping your actual content crawlable.
Business framing: unless you’re intentionally creating indexable search landing pages (rare for SMEs), internal search URLs are almost always a crawl trap.
Key caution: blocking does not guarantee the URL won’t appear in search if other pages link to it. If the goal is deindexing, you typically need a crawlable page that returns a noindex directive—robots.txt can prevent the crawler from seeing that directive.
2) Faceted Navigation And Filter URLs
Filters are where ecommerce sites either win big or bleed quietly for years.
Faceted navigation can be a legitimate SEO strategy if you deliberately create static, valuable landing pages (e.g., “black running shoes” pages that deserve to rank). But uncontrolled filtering can create:
- Duplicate category variants that add no unique value.
- “Crawl infinity” when parameters can be combined in endless ways.
- Signal dilution: internal links spread across thousands of near-identical URLs.
SEJ’s guidance is the right approach: identify which parameters create unwanted crawl space, and block only those. Don’t block facets that are part of your search strategy.
Practical inventory questions for SMEs:
- Do we want Google to rank our filter pages (color/size/material)?
- Do these filtered pages have unique content, helpful copy, or strong product selection?
- Do we have a stable set of “approved facets,” or is it user-generated chaos?
3) Action URLs: Add-To-Cart, Wishlist, Compare, Sort
Action URLs are made for users, not bots. If crawlers hit “add-to-cart” URLs at scale, it’s not just crawl waste—it can be operational risk.
SEJ references Google’s warnings about action URLs wasting resources. You should look for patterns like:
/cart/add/wishlist/add?sort=price_asc?compare=
Business framing: if the URL’s purpose is to do something rather than inform something, it’s often a candidate for crawl restriction (and sometimes for stronger access controls).
4) Account And Checkout Areas (With Care)
Account URLs and checkout flows are usually not meant for search results. But beware: some “login” pages can be useful for users to find.
SEJ provides a helpful pattern: disallow subpaths while allowing the base login page (often by using an Allow for the exact URL with $ end-of-URL marker).
Business framing: decide what you want discoverable. For many businesses, allowing /myaccount/ but blocking /myaccount/orders/ is reasonable—yet always validate that the site behaves properly and doesn’t expose sensitive links through crawlable areas.
5) Non-Rendering JavaScript: Only If You’re Sure
This is where teams get hurt.
Blocking JavaScript files can prevent crawlers from rendering pages properly, which can hide content and links from indexing. SEJ’s advice is the only safe advice: block scripts only after confirming they are unnecessary for rendering the content and internal links you need crawled.
Business framing: don’t treat JS blocking as “cleanup.” Treat it as a rendering decision with SEO consequences. When in doubt, don’t block.
6) Sitemaps: Low Effort, High Signal
Including sitemap URLs in robots.txt helps crawlers discover your sitemaps. SEJ notes that Sitemap directives require absolute URLs and you can list multiple sitemaps.
Business framing: if you’re going to touch robots.txt at all, include your sitemap locations. It’s not a silver bullet, but it improves discoverability and reduces ambiguity.
UTM Parameters: When To Leave Them Alone
UTM parameters are a classic “SEO panic” topic: people see ?utm_source= and want to block anything with a query string.
SEJ points to a John Mueller discussion about tracking parameters and emphasizes a simple distinction that most businesses miss:
- Tracking parameters (like UTM) are often attached to marketing links and should be managed by canonicalization and internal linking discipline.
- Functional parameters (like filters, internal search, sort orders) can create crawl traps and may be worth blocking.
My operational advice for SMEs:
- Don’t blanket-disallow all query parameters.
- Keep your internal links pointing to clean, canonical URLs you want crawled.
- Block parameters based on what they do on your site, not based on aesthetics.
PDFs And Non-HTML Assets: Crawl, Index, Or Noindex?
Many businesses publish PDFs: brochures, spec sheets, menus, whitepapers, compliance docs.
SEJ provides a pattern for blocking PDFs with an end-of-URL match ($.pdf). The bigger strategic question is: do you want PDFs in search?
Consider:
- If PDFs drive leads (e.g., a clinic intake form, a B2B spec sheet), you may want them indexed—or you may want the HTML page to rank and the PDF to be a secondary asset.
- If PDFs are outdated or duplicative, indexing them can create a bad landing experience and brand confusion.
SEJ makes an important point: if your goal is to keep a PDF out of search, blocking crawling may not be sufficient. You typically need an X-Robots-Tag: noindex header on the PDF while keeping it crawlable so the crawler can read the header. (Implementing that depends on your server/CDN setup.)
Business framing: “block PDFs” is not a strategy. Decide which assets are customer-facing, which are sales-facing, and which are internal. Then apply the correct technical control: crawl rules, noindex headers, or authentication.
AI Bots: Separate Training From Retrieval (And Don’t Guess)
This is the section most teams are unprepared for, even if they think they’re “doing AI SEO.”
SEJ’s guide outlines a practical approach: treat AI training crawlers differently from AI search/retrieval crawlers and user-requested bots.
Why this matters:
- Training access is about content usage rights and competitive risk. Publishers may not want reporting or original content used for training without attribution.
- Retrieval access is about distribution and citations. If an AI tool can retrieve your content for a user, it may cite you or send traffic.
- User-requested fetches are a separate category. Some providers document that user agents acting on behalf of users may not follow robots.txt the same way (SEJ provides a table summarizing documented behavior for several user-requested bots).
Build A Policy, Not A Reaction
Most companies are making ad hoc decisions like: “Block all AI bots.” That’s understandable, but it’s not a policy. A policy answers:
- Do we allow AI retrieval so our pages can be cited in AI answers?
- Do we allow AI training? For all content or only certain directories?
- Do we differentiate between product content vs editorial content?
- What’s our stance on user-requested access (where robots.txt may not apply)?
Use Documented User-Agent Tokens When Available
SEJ cites examples of user-agent tokens for OpenAI and Anthropic crawlers and provides sample groupings that block training while allowing search and user agents. The strategic lesson isn’t the exact file syntax—it’s the approach: separate rules for different bot purposes.
Two major cautions:
- Robots.txt is voluntary. Compliant bots follow it; malicious scrapers may ignore it. Don’t confuse robots.txt with enforceable access control.
- Provider behavior evolves. If a provider’s documentation changes, your policy may become outdated. That’s why monitoring server logs and staying current matters.
Google-Extended And Applebot-Extended: Usage Control, Not Crawl Reduction
SEJ highlights an important nuance: tokens like Google-Extended and Applebot-Extended relate to how content is used (e.g., training/grounding policies) rather than being distinct crawlers that reduce crawl volume. Blocking these tokens may not reduce requests like a Disallow for Googlebot would; it’s a content-usage directive.
Business framing: this is governance. Decide what you permit your content to be used for, then implement the documented controls and validate via monitoring where possible.
Crawl-Delay, Rate Limiting, And When Robots.txt Is Not Enough
Robots.txt is a request, not an enforcement mechanism.
SEJ notes that Crawl-delay is not supported by Googlebot, but may be respected by other crawlers (Anthropic documents support for crawl-delay in SEJ’s write-up). That means crawl-delay is situational: helpful for certain bots, irrelevant for others.
For many SMEs, the more practical reality is:
- If a bot overloads your server, you may need CDN or firewall-based rate limiting.
- If content must be private, you need authentication, not robots.txt.
- If a provider’s user-requested agent ignores robots.txt, you need stronger controls (or accept that user-driven retrieval is part of the open web, depending on your stance).
Testing And Troubleshooting: Don’t Deploy Blind
Robots.txt failures are usually discovered the wrong way: rankings drop, traffic drops, or product pages disappear from the index.
SEJ recommends using Google Search Console’s robots.txt reporting to validate syntax and fetch behavior. That’s table stakes.
My practical testing stack for any robots.txt change:
- Pre-change snapshot: export current robots.txt and store it (version control if possible).
- List your critical URLs: top product categories, top lead-gen pages, top blog posts, CSS/JS assets needed for rendering.
- Test patterns explicitly: don’t assume your wildcard works—validate against the actual URLs your site generates.
- Deploy and immediately verify:
- Fetch robots.txt (make sure it’s accessible, not cached incorrectly).
- Use Search Console where available to confirm Google sees it.
- Monitor server logs: verify which bots are hitting which paths and what response codes they get.
- Watch index coverage and crawl stats: spikes in “discovered but not indexed,” crawl anomalies, or resource fetch issues can indicate problems.
If your team doesn’t have server log access, that’s not a deal breaker—but it is a constraint you should acknowledge. In those cases, your CDN logs, hosting analytics, or security tooling may be your best option.
The SME Scenario: An Ecommerce Store Accidentally Blocks Revenue Pages
Let’s make this concrete.
Scenario: a mid-sized ecommerce store sells home fitness equipment. They have:
- Category pages (indexable, revenue-driving)
- Filter parameters (color, brand, resistance level, sort order)
- Internal search
- PDF manuals and spec sheets
The problem: the team notices Google crawling thousands of filter URLs, so they “quick fix” robots.txt by blocking anything with a query string. It looks like this in spirit:
- Disallow: /*?* (blanket rule)
What goes wrong:
- Many of their canonical category URLs actually rely on query parameters for pagination or for core category experiences.
- Some internal links include tracking parameters (UTMs) on important pages; now crawlers can’t access those variants and can’t see canonical tags on them.
- Google can still index some blocked URLs based on links, but now it can’t crawl content to understand canonicalization signals. Index quality degrades.
Business impact: the store sees organic landings shift toward poorer pages, product discovery slows, and conversions drop—not because products changed, but because crawl control was applied without a policy.
The fix (what they should have done):
- Block internal search parameter(s) only (e.g.,
s=patterns). - Block specific filter parameters known to create duplicates (e.g.,
sortby,color, etc.), aligned with their SEO strategy. - Keep canonical category URLs crawlable.
- Use
X-Robots-Tag: noindexfor PDFs they don’t want indexed (instead of blocking crawl). - Verify with Search Console and logs.
This is why I keep saying: robots.txt is less about “knowing the directives” and more about “knowing your business URLs.”
A Practical Action Plan: Your Robots.txt Policy In 30–60 Minutes
If you only do one thing after reading this, do this: write down a robots.txt policy you can explain to a non-SEO stakeholder.
Step 1: Define Your Crawl Goals
- SEO goal: which sections must be crawlable and indexable?
- Efficiency goal: which URLs are pure crawl waste?
- AI goal: do you allow training, retrieval, both, or neither?
Step 2: Inventory Your URL Patterns
Create a simple list:
- Internal search patterns
- Filter/sort parameters
- Action URLs
- Account/checkout paths
- File types (PDF)
- API endpoints and form submission paths
Don’t start writing robots rules until this list exists.
Step 3: Write Minimal, Specific Rules
Prefer targeted rules over blanket patterns. Use Allow exceptions only when you can test them and explain them.
Step 4: Add Sitemap Directives
Include absolute sitemap URLs. If you have multiple sitemaps, list them all.
Step 5: Test Before And After Deployment
- Validate the robots file is reachable and not returning errors.
- Use Google Search Console robots reporting where available.
- Spot-check critical URLs.
Step 6: Monitor And Iterate
Robots.txt is not “set it and forget it” anymore. Your site changes. Bots change. Your strategy changes.
Monitoring should include:
- Crawl behavior shifts (spikes in weird URLs)
- Index coverage anomalies
- Server load anomalies tied to bot traffic
- AI bot access patterns (especially if you change training/retrieval policies)
Where AYSA Fits: Monitoring + Approved Execution For Crawl Policy
Most robots.txt incidents are not due to lack of knowledge—they’re due to lack of execution control:
- Someone edits robots.txt directly in production.
- An agency pushes a template rule that doesn’t match your CMS reality.
- A platform update changes URL patterns and your old rules become dangerous.
This is where AYSA is designed to help: it’s an approved SEO/AEO/GEO execution system that monitors what’s happening, prepares the changes you should make, asks for approval, and then executes accepted website changes with verification.
Concretely, robots.txt work fits AYSA’s model because it benefits from:
- Ongoing monitoring of crawl anomalies and indexation risks (AYSA Monitoring).
- AI search visibility planning that treats retrieval vs training as separate policies (AI Search Visibility).
- Repeatable technical SEO workflows that reduce “hero debugging” (AYSA AI SEO Tools).
- Approval gates so stakeholders sign off on training vs retrieval decisions before they ship.
- Documented change history so you can roll back safely and understand why a rule exists.
If you’re running robots.txt as an untracked, manual file, you’re accepting an avoidable operational risk. In 2026, the right standard is: treat crawl policy like a production configuration—managed, reviewed, and monitored.
If you want to see how AYSA is packaged for teams, start here: AYSA Pricing and the broader editorial library: AYSA Blog.
What To Do Next
- Pull your current robots.txt and store a dated copy (version it).
- List your top 20 revenue/lead URLs and confirm none are blocked (including assets needed to render them).
- Identify your crawl traps: internal search, facets, sorts, action URLs.
- Decide your AI stance: training vs retrieval vs user-requested access. Get stakeholder sign-off.
- Update robots.txt with minimal, specific rules, plus sitemap directives.
- Test in Google Search Console (where available) and spot-check critical URLs.
- Monitor crawl and index behavior for 2–4 weeks. Don’t assume success on day one.
- Operationalize it: make robots.txt changes go through an approval and verification workflow (AYSA can help).
Sources And Further Reading
- Search Engine Journal: Robots.txt Guide – Best Practices For Search & AI Crawlers
- Search Engine Journal: Technical SEO
- Search Engine Journal: AI Search
- Search Engine Journal: Google Updates (algorithm history and changes)
- AYSA.ai: AI Search Visibility
- AYSA.ai: AI SEO Tools
- AYSA.ai: Monitoring
- AYSA.ai: Pricing
- AYSA.ai: Blog
Continue the AI search topic inside AYSA.
Use these pages to connect the article with AI SEO tools, AI visibility monitoring, AI Overviews and approved website execution.
Turn this topic into a website action plan.
Use these AYSA hubs to move from reading to technical fixes, AI visibility monitoring, research, glossary context and approval-first SEO execution.