Temporary Downtime, Permanent Damage: The 503, Robots.txt, URL Encoding, And Image Format Traps That Break SEO (And AI Search) In 2026
Google’s latest reminders aren’t random: 503s, robots.txt scope limits, bracket URL encoding, JPEG XL gaps, and agent behavior all point to one reality—search visibility is now controlled by operational hygiene. Here’s what changed, why it matters, and an execution-first plan you can run with AYSA.
Search has entered an operations era. The biggest SEO wins (and losses) now come from small, unglamorous technical signals that tell crawlers, AI systems, and agent-like browsers what they can access, what they should index, and what they should preview.
This matters because the web is no longer consumed only through “Google Search results.” Your pages are being fetched by multiple systems with different rules: traditional crawlers, user-triggered fetchers, preview generators (Images/Discover), and AI assistants that may browse pages or rely on protocol-based access. If your technical signals are inconsistent, you don’t just risk losing rankings—you risk disappearing from the answer layer entirely.
This editorial is based on research and reporting from Search Engine Journal, plus the primary standards and documentation referenced there. I’m writing this from the perspective of building execution systems for SMEs at AYSA.ai: Monitoring reality, proposing fixes, getting approval, and then shipping changes safely.
Concise Summary
Google and adjacent ecosystem updates in late 2026 reinforce five practical truths:
- Maintenance should return a 503 (briefly) to protect Indexing—especially during emergency patch windows.
- Robots.txt governs Crawling, not downstream usage of content after it’s fetched (e.g., training/grounding). Usage controls are evolving, not standardized.
- Discovery signals don’t equal permission: systems can learn your pages exist without being allowed to fetch them.
- Reserved characters matter: raw brackets and percent-encoded brackets are different URLs and can split signals if you’re inconsistent.
- New image formats can lag in preview systems: JPEG XL might work in browsers but still fail in Google Images/Discover previews unless you provide supported fallbacks.
Key Takeaways (What You Should Do This Week)
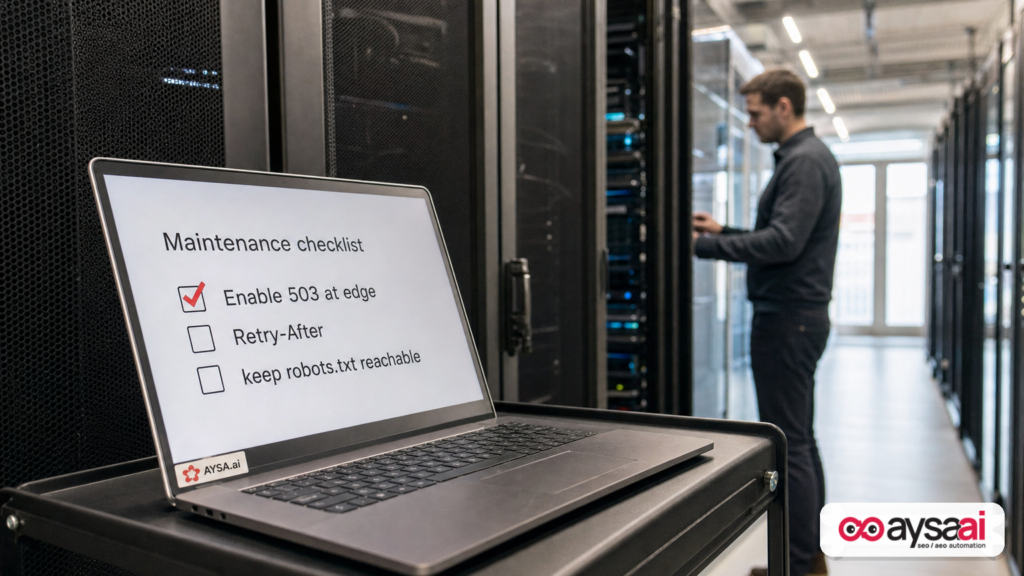
- Establish a maintenance runbook that uses 503 + Retry-After for short outages and avoids “soft 200” maintenance pages.
- Audit your robots.txt strategy by separating (1) crawl access from (2) content usage preferences—and document what you’re trying to achieve.
- Normalize URL handling: pick encoded reserved characters for any new work, and ensure canonicals, sitemaps, internal links, and Structured data match.
- Do not ship JPEG XL-only assets for SEO-critical previews; use picture element fallbacks and ensure img src points to a supported format.
- Update monitoring: watch status code patterns, robots.txt changes, odd URL variants, and image preview eligibility signals.
Table of Contents
- The New Reality: Search Visibility Depends On Operational Signals
- 503 During Maintenance: The Small HTTP Detail That Prevents Big Index Loss
- How To Serve A 503 When PHP Is Down (Without Breaking Everything Else)
- Robots.txt Isn’t An AI Usage Contract—It’s A Crawl Access Preference
- Google-Extended, GPTBot, OAI-SearchBot: What You Can (And Can’t) Control
- Discovery vs Permission: Why “Found” Doesn’t Mean “Cited”
- Brackets In URLs: Raw vs Encoded Can Split Ranking Signals
- A Practical URL Normalization Plan For SMEs
- JPEG XL Reality Check: Browser Support ≠ Search Preview Support
- AI Agents Will Browse And Use Protocols: What That Means For Your Site
- Concrete SME Scenario: Ecommerce Maintenance + AI Visibility Gone Wrong
- What To Monitor: The Minimal Alert Set That Prevents Silent Losses
- Where AYSA Fits: Monitoring → Recommendations → Approved Execution
- What To Do Next (Action List)
- Sources And Further Reading
The New Reality: Search Visibility Depends On Operational Signals
For years, SEO conversations centered on “content vs links vs technical.” In 2026, that framing is incomplete. The bigger shift is that visibility is negotiated through operational signals across many systems:
- Traditional crawlers that discover and fetch pages over time.
- Indexing systems that decide what to keep when they see errors repeatedly.
- Preview systems (Images, Discover, link previews) that require specific formats and metadata.
- AI assistants that may use search indexes, browse pages directly, or rely on protocols and feeds.
Each of the updates highlighted by Search Engine Journal points to the same core lesson: you don’t “do SEO” once; you run SEO continuously. That’s why we built AYSA around monitoring and execution: detect drift, prepare fixes, request approval, and then ship safely.
When these signals break, the failure mode is usually silent. Rankings don’t always crash immediately. Instead you get:
- Indexation decay after repeated “temporary” errors become “persistent” in the eyes of systems.
- Duplicate URLs that split authority and confuse reporting.
- Preview eligibility issues that reduce Clicks even when rankings stay steady.
- AI answers that stop citing you because your pages are harder to fetch consistently.
503 During Maintenance: The Small HTTP Detail That Prevents Big Index Loss
Google Search Central reminded site owners to use HTTP 503 Service Unavailable during brief downtime—specifically in the context of emergency PHP patching. Search Engine Journal reported the reminder and emphasized Google’s guidance that 503s shouldn’t be served for multiple days, or URLs may be dropped from the index.
What changed isn’t the meaning of 503; it’s the urgency. Security patching is happening more often, and teams increasingly rely on quick “maintenance pages” that accidentally return:
- 404 (making the system think the content is gone), or
- 200 with a “maintenance message” (a soft failure that can be indexed as the page content), or
- Blocked robots.txt responses (which can halt crawling entirely depending on how it’s configured).
Google’s operational expectation is simple: if the outage is temporary, say so with the right status code. It’s a machine-to-machine communication problem.
Why 503 Helps (In Plain English)
Think of Google as a logistics network. If it tries to deliver to your address and sees:
- 404: “This address does not exist anymore.” It starts removing it from maps.
- 200 with “We’re closed”: “This is the new experience at this address.” It may index the “closed” message.
- 503: “We’re temporarily unavailable; try again later.” It tends to keep the address and retry.
That “retry” behavior is not infinite. The longer you serve 503, the more likely systems decide it’s no longer temporary.
The Real Risk: You Think You’re Doing Ops, Google Thinks You’re Deleting Pages
The most damaging downtime mistakes don’t come from the outage—they come from the wrong substitute response. During patch windows, teams often implement quick rules that aren’t tested against SEO-critical URLs such as:
- category pages, service pages, location pages, product pages
- sitemaps, robots.txt, and key assets needed for rendering
- APIs used by your frontend (if the site becomes half-broken, you can end up returning 200 with empty content)
That’s why you need a runbook, not a Slack message.
How To Serve A 503 When PHP Is Down (Without Breaking Everything Else)
Search Engine Journal’s summary included an important operational detail attributed to John Mueller: the 503 doesn’t have to be served through PHP. That’s the point—when your app runtime is down, you need a layer that can still respond correctly.
Common options include:
- CDN / edge rule that responds with 503 for all requests (or a controlled subset).
- Load balancer / reverse proxy maintenance mode that returns 503 before traffic hits the app.
- Temporary origin (DNS switch) that serves a 503 response.
A Safe 503 Maintenance Checklist
Use this as an operational baseline. Adapt it to your stack.
- Return 503 for affected pages; avoid 404 and avoid 200 “maintenance” pages.
- Add Retry-After header where possible (minutes/hours). (This is an HTTP standard mechanism; implementation varies.)
- Keep robots.txt reachable and stable. If you accidentally serve 503 to robots.txt, you may block crawling depending on how systems interpret it.
- Keep critical verification endpoints stable (e.g., do not break your canonical host, do not change redirect logic).
- Time-box the outage. Google’s public guidance (as referenced by SEJ) indicates multiple days of 503 can lead to index dropping; plan maintenance windows accordingly.
- Post-maintenance validation: check key pages return 200, canonical tags are present, sitemaps fetch, and you did not introduce mixed URL formats (more on that later).
What Not To Do
- Don’t blanket redirect everything to the homepage with 302/301. That’s not “maintenance,” that’s URL replacement.
- Don’t show a branded maintenance page with 200 across your site. You’re telling crawlers the maintenance message is your content.
- Don’t change robots.txt during a crisis unless you know exactly why. You can lock yourself out of crawling recovery.
Robots.txt Isn’t An AI Usage Contract—It’s A Crawl Access Preference
Gary Illyes of Google emphasized a point that many businesses still misunderstand: standard robots.txt directives define what compliant crawlers may crawl. They do not define how content can be used after it has been crawled.
This distinction matters more in 2026 than it did in 2016. Why? Because the “post-crawl lifecycle” now includes:
- indexing and ranking (classic search)
- preview generation (Discover, Images, Rich results)
- AI grounding and assistant responses
- model training (depending on the provider and the system)
Illyes referred to robots.txt as an “access preference protocol,” aligning with the intent of the robots exclusion standard.
The Standard: RFC 9309 (Robots Exclusion Protocol)
For the underlying standard, see RFC 9309. The key idea to internalize is: robots.txt is about fetching (crawl access). It is not a universal rights management file. It does not retroactively govern what happens to content that has already been fetched or obtained elsewhere.
Business Implication: Robots.txt Is Necessary—but Not Sufficient
SMEs often want a single switch for: “Search can index us, but AI can’t use us,” or “AI can cite us, but not train on us,” or “We want to be visible in assistants but not scraped.”
The uncomfortable truth is: the ecosystem doesn’t offer a single standardized control for every outcome. Some providers offer specific tokens or separate crawlers; some distinguish between “search” and “training”; some systems discover URLs via third-party signals; and some “user-triggered fetchers” may not treat robots.txt the way you expect.
That’s why your policy must be explicit: are you trying to prevent crawling, prevent training, influence citations, reduce load, or protect gated content? Those are different objectives requiring different controls.
Google-Extended, GPTBot, OAI-SearchBot: What You Can (And Can’t) Control
Search Engine Journal noted Google’s documentation around Google-Extended, a token you can use in robots.txt to manage whether content Google crawls may be used for training and grounding in certain Gemini contexts—without affecting inclusion in Google Search.
Important nuance from the SEJ summary: Google-Extended is a token, not a separate crawler with its own user-agent string. That matters because it changes how you reason about enforcement and measurement.
On the OpenAI side, SEJ referenced that OpenAI documentation distinguishes between search and training, with examples such as allowing OAI-SearchBot while disallowing GPTBot—a pattern that many publishers and SMEs are adopting when they want discovery/citation but not training.
Actionable takeaway: build a policy matrix for your business.
A Simple Policy Matrix (SME-Friendly)
Write down which outcomes you want:
- Be indexed in Google Search (usually yes)
- Appear in AI answers with citations (often yes for demand generation)
- Allow AI search crawlers to fetch your public pages (maybe)
- Allow training on your content (depends on your moat and industry)
- Protect gated content (almost always yes)
Then align controls accordingly—robots.txt, authentication, paywalls, rate limits, structured data, and content strategy. Don’t pretend robots.txt alone solves a policy problem.
The “Content-Usage” Concept Is Still Emerging
SEJ reported that a draft co-authored by Illyes would add a Content-Usage rule to robots.txt to state usage preferences. The key word is “draft.” Until such a proposal becomes a standard (and widely implemented), treat it as directionally interesting, not operationally reliable.
If you need stronger assurances today, your best bet is to combine:
- clear technical access controls (auth, paywalls, bot management)
- explicit licensing terms and contracts where relevant
- provider-specific tokens where supported
And then monitor actual bot activity in logs.
Discovery vs Permission: Why “Found” Doesn’t Mean “Cited”
One of the more subtle shifts reported by SEJ is that discovery mechanisms can expand rapidly without granting access rights. In the Cloudflare/OpenAI pilot described by SEJ, the point was to help a crawler identify pages more efficiently—avoid dead ends, detect updates, and discover new URLs. But even SEJ’s summary stresses a key line: a signal about a page doesn’t grant permission to access it.
That distinction is crucial for businesses because many teams conflate three different events:
- Discovery: a system learns a URL exists.
- Fetching: a system requests and downloads the content.
- Utilization: a system indexes, summarizes, trains, or cites.
You can influence fetching with access controls and robots directives (for compliant systems). You can influence utilization with provider-specific tools and metadata. But you cannot assume that being discovered guarantees traffic, citations, or any measurable business benefit.
What This Means For AI Visibility (AEO/GEO)
If you care about being the cited source in AI answers, your work is less about “getting found” and more about “being the best, cleanest, most retrievable answer.” That means:
- stable URLs
- fast, consistent rendering
- clear entity signals and structured data where appropriate
- accessible pages (not accidentally blocked during patch windows)
At AYSA, we treat AEO/GEO as an execution problem as much as a content problem. Visibility changes when you ship changes, not when you discuss them.
Brackets In URLs: Raw vs Encoded Can Split Ranking Signals
This is the kind of technical nuance that sounds minor—until you realize it can fragment your entire site’s indexing.
SEJ reported John Mueller’s clarification: raw square brackets in a URL and their percent-encoded forms (%5B and %5D) are different URLs. Mueller referenced the URI syntax standard RFC 3986, which defines reserved characters and encoding rules.
In plain terms: these two are not the same address to a crawler:
https://example.com/page[1]https://example.com/page%5B1%5D
Why It Matters
If you mix these formats across:
- internal links
- canonical tags
- XML sitemaps
- structured data URLs
- hreflang (if applicable)
…you are effectively telling systems that multiple URLs represent the same thing. Google may crawl both, attempt deduplication, and pick one canonical on its own—but you’ve still created unnecessary crawling, reporting ambiguity, and the risk of inconsistent canonical selection.
Where Bracket URLs Show Up In Real Businesses
- Ecommerce filters: color[blue], size[large], etc.
- Search and faceted navigation that generates bracket parameters.
- Legacy CMS plugins that produce non-standard URL patterns.
- APIs that serialize nested parameters into brackets.
Sometimes the bracket URLs are not public-facing on purpose—they leak via internal search, onsite filtering, or tracking links.
Mueller’s Practical Advice: Pick One
SEJ reported Mueller’s recommendation: choose one format and use it consistently everywhere. He also noted that if a site already uses raw brackets throughout, it will likely keep working—but he wouldn’t set up a new site like that.
That’s a reasonable operational posture: avoid introducing new technical debt.
A Practical URL Normalization Plan For SMEs
If you suspect you have this problem (or want to ensure you don’t), here’s an execution plan that SMEs and agencies can actually run.
Step 1: Inventory Where URLs Come From
- CMS routing rules
- frontend app router
- filter/facet system
- sitemap generator
- structured data templates
- marketing tagging / UTM builders
You can’t fix URL consistency by only changing canonicals. The source of truth must be aligned.
Step 2: Pick A Canonical URL Format
For reserved characters, the conservative approach is: percent-encode where standards require encoding. Avoid introducing raw brackets in new implementations.
Step 3: Enforce Consistency Everywhere
- Internal links: only one format.
- Canonical tags: only one format.
- Sitemaps: only one format.
- Structured data: only one format.
If your stack can generate both, you will reintroduce the problem every time templates are updated.
Step 4: Handle Duplicates Carefully
If both URL variants are accessible, you need a consistent strategy. Depending on risk and implementation feasibility, common approaches include:
- 301 redirects from the non-canonical to the canonical (preferred when safe).
- Canonical tags to consolidate (works, but still wastes crawl).
- Parameter handling rules where applicable.
Be careful: in some systems, aggressively redirecting filter URLs can break user experience. This is why SMEs should treat URL normalization as an engineering + SEO joint task.
Step 5: Validate With Search Console And Logs
Even without fancy tooling, you can learn a lot by checking:
- Index coverage patterns and URL examples in Google Search Console.
- Server logs for repeated crawling of duplicated URL patterns.
AYSA’s approach is to monitor patterns continuously, because these issues often reappear after releases.
JPEG XL Reality Check: Browser Support ≠ Search Preview Support
JPEG XL is a modern image format with growing browser support. But SEJ reported John Mueller’s note that JPEG XL isn’t supported in Google Images or Discover previews (at least at the time referenced).
This is a classic trap for teams that optimize for:
- Core Web Vitals
- bandwidth savings
- modern browser features
…and assume search preview systems move at the same pace. They don’t.
Google’s Supported Image Formats (For Search)
SEJ referenced Google’s image SEO documentation listing supported formats (BMP, GIF, JPEG, PNG, WebP, SVG, AVIF) for images in an img element’s src attribute. See Google’s image SEO guidance here: Google Search: Images documentation.
If your SEO-critical pages rely on images for previews, you should assume the supported list is the ground truth until Google updates it.
The Practical Fix: Use picture With A Supported img src
Mueller’s comment (as reported by SEJ) points to a pragmatic implementation pattern:
- Serve JPEG XL as an optional source in a
pictureelement for browsers that support it. - Keep the
imgelement’ssrcset to a supported format (JPEG/WebP/AVIF).
This lets you benefit from modern formats without breaking search previews.
Discover And Social Previews: Don’t Forget og:image
Discover preview images are influenced by metadata like og:image and relevant schema markup (as SEJ noted). The operational rule is simple: your metadata should point to a widely supported format. If you point og:image to JPEG XL only, you’re taking an unnecessary risk.
AI Agents Will Browse And Use Protocols: What That Means For Your Site
SEJ also reported comments from Google CEO Sundar Pichai suggesting AI agents will access websites both by browsing like humans and via protocols designed for agents, with protocols being “more scalable” but slower to develop.
You don’t need to overinterpret that to get value from it. The operational takeaway is straightforward:
- Browsing-based access isn’t going away. Pages still matter.
- Protocol-based access is coming (for commerce and other tasks). Feeds, structured endpoints, and standardized interactions will likely grow in importance.
The Risk Zone: User-Triggered Fetchers And Robots.txt Expectations
SEJ noted that Google’s user-triggered fetchers (e.g., systems that fetch content on behalf of a user action) generally ignore robots.txt rules. That can surprise teams who assume robots.txt is a universal barrier.
What to do with that information:
- Use robots.txt for what it is: crawl preference for compliant crawlers.
- Use authentication and authorization for what they are: access control.
- Use monitoring and rate limiting to detect unusual patterns.
Concrete SME Scenario: Ecommerce Maintenance + AI Visibility Gone Wrong
Let’s make this real with a scenario I see constantly—just with different industry labels.
Scenario: A Mid-Market Ecommerce Brand Patches PHP Before A Peak Weekend
A growing ecommerce company selling specialty outdoor gear runs on a PHP-based stack. A security advisory drops mid-week. Engineering schedules a quick patch window Friday night.
They do the responsible thing—patch quickly. But they implement a maintenance page that returns 200 because it’s served by the CDN as a static HTML page. They also temporarily block traffic to reduce load by returning 503 for /robots.txt (unintentionally, because the CDN rule is too broad).
What Happens Next
- Googlebot hits key product pages and sees a 200 maintenance message. Some pages get reprocessed with thin “maintenance” content signals.
- Googlebot requests robots.txt and gets 503. Crawling slows or stalls.
- The next week, their SEO team sees weird volatility: some products drop, some stay, reporting gets messy.
- Meanwhile, their team tests JPEG XL to improve performance and points
og:imageto JPEG XL only. Discover traffic falls because previews fail. - Faceted filters generate bracket URLs; mixed linking causes duplicated crawling and canonical confusion.
How This Should Have Been Handled
- A controlled maintenance rule returning 503 + Retry-After, not a 200 page.
- Explicit exceptions so robots.txt remains reachable (and ideally continues to return 200).
- Image format changes shipped with safe fallbacks (
pictureand supportedimg src, metadata pointing to supported formats). - URL normalization enforced at template and sitemap level.
This isn’t “SEO theory.” It’s operational discipline. And it’s exactly the type of discipline SMEs struggle with because they don’t have time to translate SEO requirements into dev-ready tasks and then deploy them safely.
What To Monitor: The Minimal Alert Set That Prevents Silent Losses
You don’t need 200 dashboards. You need the right handful of alerts that catch invisible failures early.
1) Status Code Drift (Especially 503)
- Alert when key templates (homepage, top categories, top services, top products) return non-200.
- Alert if 503 persists beyond the planned window.
- Track robots.txt separately; it’s a small file with big consequences.
2) Robots.txt Change Detection
- Alert on any robots.txt modification (intentional changes should be tracked like deployments).
- Keep a version history and rollback plan.
3) URL Variant Explosion
- Detect when new URL patterns appear (encoded vs raw, parameter variations).
- Watch sitemap vs crawl vs index mismatches.
4) Preview Asset Eligibility
- Confirm your metadata images (
og:image) are in supported formats. - Audit templates after performance “optimizations” that change file formats or sources.
5) Bot And Agent Fetch Patterns (Logs)
- Know which user-agents are requesting what paths.
- Look for spikes after discovery events or news cycles.
- Separate “search crawling” patterns from “user-triggered fetching” patterns where possible.
Where AYSA Fits: Monitoring → Recommendations → Approved Execution
Most businesses don’t fail at SEO because they don’t know “best practices.” They fail because execution is inconsistent:
- Marketing notices an SEO issue but can’t ship changes.
- Engineering ships a fix but misses SEO details (canonicals, status codes, metadata).
- Ops changes CDN rules during an incident and doesn’t consider crawlers.
AYSA is built to close that execution gap.
1) Monitor The Signals That Actually Move Visibility
AYSA continuously monitors technical and visibility signals so you don’t find out after traffic drops. See: AYSA Monitoring.
2) Prepare Fixes That Non-SEO Teams Can Implement
Instead of vague “SEO recommendations,” AYSA turns issues into concrete change proposals: what to change, why it matters, and what could break. Explore AYSA’s AI SEO tooling approach: AI SEO Tools.
3) Ask For Approval Before Shipping
SEO changes are operational changes. That means approvals, audit trails, and rollbacks. This is where the “approved execution” model matters: you stay in control of risk while still moving fast.
4) Execute Accepted Changes (And Verify)
Execution without verification is just hope. After changes ship, AYSA verifies the signals again: status codes, canonicals, preview assets, and crawl behaviors.
5) Tie It Back To AI Search Visibility (AEO/GEO)
As assistants and agents expand, your ability to be retrieved reliably becomes part of your brand demand. Learn more about how AYSA frames AI visibility: AI Search Visibility.
If You Want This As A System, Not A One-Off Project
Most SMEs don’t need an “SEO overhaul.” They need a persistent execution layer. See pricing and fit: AYSA Pricing. And for more editorials like this, visit: AYSA Blog.
What To Do Next (Action List)
- Create a maintenance protocol: define how you will return 503, where it’s enforced (edge/proxy/origin), and who approves it.
- Test maintenance mode quarterly: run a 10-minute “maintenance drill” that validates correct responses for pages, robots.txt, sitemaps, and key assets.
- Audit robots.txt with a policy lens: write down your intended outcomes (crawl vs training vs citation) and align directives accordingly.
- Normalize URL encoding: find any raw/encoded bracket variants and choose a consistent canonical approach across links, canonicals, sitemaps, and structured data.
- Harden your image preview pipeline: ensure Google-supported formats are used in
img srcand metadata likeog:image; usepicturefor progressive enhancement. - Review logs monthly: confirm the bots hitting your site match your expectations; investigate spikes and odd crawl paths.
- Automate monitoring + execution: set alerts for status drift, robots.txt changes, URL variant growth, and preview asset failures—then ship fixes through an approval workflow.
Sources And Further Reading
- Search Engine Journal (research input): Google Explains 503s, Robots.txt Limits & Bracket URLs – SEO Pulse
- RFC 9309 (Robots Exclusion Protocol): rfc-editor.org: Rfc9309
- RFC 3986 (URI Generic Syntax): rfc-editor.org: Rfc3986
- Google Search documentation (Images): developers.google.com: Google Images
- Search Engine Journal topic hub (AI Search): searchenginejournal.com: Generative Ai
- Search Engine Journal topic hub (Technical SEO): searchenginejournal.com: Technical Seo
- Search Engine Journal topic hub (SEO News): searchenginejournal.com: News
Note on verification: Several ecosystem-specific controls (e.g., provider tokens and exact crawler behaviors) evolve quickly. When implementing policy decisions, confirm current documentation for each provider and validate behavior in server logs.
Continue the AI search topic inside AYSA.
Use these pages to connect the article with AI SEO tools, AI visibility monitoring, AI Overviews and approved website execution.
Turn this topic into a website action plan.
Use these AYSA hubs to move from reading to technical fixes, AI visibility monitoring, research, glossary context and approval-first SEO execution.